You see the fear in my eyes and still I'm standing. I'm never going to stop reaching, reaching. Even when my hands start bleeding, every little scar is a reason. I'm still never going to stop trying.
If I fall tonight, I'll have all my failures on my side. Like a choir for my life, singing one more time. One more time. I'm never going to stop trying.
Even when the waves keep rising, rising, you can see the fear in my eyes. And still I'm standing. I'm never going to stop reaching, reaching. Even when my head start bleeding, every little scar is a reason I'm still standing. Never going to stop trying.
On my face like I painted the sun with the begging for fun. Watch me light it up. I'm second to none. I'm rising up. I'm rising up now.
I'm the sparkle. Fire from the soul. In my stride like I'm born for the stage. I'm turning the page. In my presence never play safe. Catch me in the moment and run away. I'm turning up. I'm turning up now.
Oh, I'm the sparkle. Fire on the soul. I'm the fire. I'm the soul.
Come turning up now. Oh. Oh. Oh. I'm the sparkle.
Hey. Yeah.
Phone face down. Still I keep on checking. Mind runs wild. Every scene projecting. Got your name doodled on my playlist. If this is wrong, I kind of want to stay. I can't wait to see this play out in real life. Us in the front row, laughing through the late nights. I can't wait to feel it. First love, first kiss. Whatever this becomes. I can't wait to see this.
You say something. Yeah. You always say it. I hiss and then I'll be what I am when you smile even through a screen glow whole face I'm ready just to let go. I can't wait to see this play out in real life in the front row laughing through the late nights I can't wait to feel it first kiss whatever this becomes I can't wait to see this.
What if it's better than all my daydreams? What if you're braver than I believe? Say meet me outside and I won't resist. I've waited all this time. Can't wait for this. I can't wait to see this play out real life in the front row.
This is how intelligence is made. A new kind of factory, generator of tokens, the building blocks of AI. Tokens have opened a new frontier, turning data into knowledge, reason, action. They reveal patterns in complexity we could never see. Mirror our cities to keep us safe and lift us high above them. Tokens help robots learn from us, work alongside us. They go where we cannot. Lending us helping hands and closing the gap between hope and healing so that we breathe easier. And the smallest hearts beat stronger.
Tokens are helping us break new ground on a scale never attempted so we can reach Starcloud one. Separation confirmed to infinity and beyond. Together we take the next great leap into a bright new future built for all mankind. And here in Taipei is where it all begins.
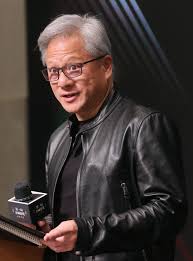
Welcome to the stage Nvidia founder and CEO Jensen Huang.
Welcome to GTC Taiwan. So great to see all of you. Very good to be home. I brought my parents home. Where are my parents? Everybody give round of applause to my mom and dad.
And a round of applause for our pregame show superstars. Ladies and gentlemen, look how adorable they are. The superstars of Taiwan. There are so many of you here today. We are broadcasting this right now to 70 other watch parties across Taiwan. 70 different conferences are going at the same time. Everybody is watching this keynote. We have so much to tell you and I have so many partners to thank. It is incredible how large our ecosystem in Taiwan has become. Most of the time when people think about ecosystem, they think about our software stack. They think about the developer ecosystem above the computing systems that Nvidia builds. But Nvidia's ecosystem spans all the way upstream to all of our supply chain here in Taiwan where it all begins and downstream all the way to data centers and eventually to end users. Today we're going to talk about almost all of the ecosystem. There's so many people to thank. I love my ecosystem here. I mean, there are so many companies here and some of my favorite ecosystem partners.
So many Taiwan's rich ecosystem, the richest ecosystem, the world's best supply chain ecosystem. Unbelievable. Well, thank you all for being here and this year our businesses together are growing incredibly. In fact, somebody told me last night that the annual GDP of Taiwan is going to grow almost 10%. Unbelievable. Well, we have a lot to talk about. Let's get going.
Two years ago when I was here, I started to talk to you about how AI has moved from generative AI and the other waves of AI that are coming. The next wave of AI was agentic AI. And today we can say that agentic AI has arrived, that useful AI has arrived. Now what does this mean? This is GitHub. This is of course one of the first applications of Agentic AI is software coding. One of the most valuable professions, incredibly large ecosystem, 30 million, 40 million professional software developers, probably another couple of hundred who are students and enthusiasts and so on so forth, but say 30 40 million software developers in the world code for a living. And this represents most of them. This is GitHub. The pull request is when they download software, they modify it, and commit is when they push it back up. Okay? And so if you could look at this in 2023, the number of commits was 300 million. 2024, 400 million. 2025, 500 million commits in the first few months. In the first few months of 2026, it has nearly tripled. Now, what does that mean? 30 million software developers representing about $3 trillion worth of GDP producing three, that's what they're paid. $3 trillion worth of salaries per year, which is generating economic growth for the rest of the industries. Say a hundred trillion dollars of the world's industries is impacted, is generated by $3 billion worth of salary. That $3 trillion, excuse me, three trillion, that $3 trillion worth of salary is now producing nearly three times as much output. It's effectively a $9 trillion productivity from $3 trillion of salaries. Does that make any sense? The difference is absolutely extraordinary. This is the potential. This is the promise of AI. The number of engineers, software engineers is actually increasing. People talk about AI reducing jobs. Complete nonsense. It's causing more software engineers to be hired. And the reason for that is very simple. If you can hire a software engineer and you could generate $9 trillion worth of productive work, why wouldn't you want to hire more software engineers? If that line was flat, then obviously people will hire fewer software engineers. But because the output is so incredible, people want to hire more software engineers. This is going to show up in our economy somehow soon. And so the first thing is useful AI has arrived. Now, what does that mean from the industry's perspective? From the industry's perspective, that means that tokens are now in extraordinary demand. Because if you could do this, you're going to want to produce more of it. And because tokens are now profitable units, tokens are now profitable units of revenues. because it is now profitable. The AI companies want to build a lot more tokens, generate a lot more tokens, build more AI factories, which is the reason why compute demand here in Taiwan has skyrocketed. It is precisely the reason why all of you are so busy and your businesses are doing so well. In fact, that looks like some of your stock price.
The compute pattern has changed. Everything has changed. So the first idea is that useful AI has arrived. AI is now a profit generator. AI is now a GDP generator. Behind it is a whole new kind of computing pattern. Not just a large language model, but an agent. Today almost everything we're going to talk about is going to be based on this. So let me take a quick moment and show you what I'm talking about inside in this is a this is an agent. It's an agent application. In the old days this would be application. This would be code and this would be operating system. application code running inside an application inside an operating system. Today it is agent which consists of a large language model or many sitting inside a harness and that harness helps it orchestrates it to do productive work. This is the input. When that input comes, it has to understand, observe, reason, act, use tools. Use tools. That tool could be a spreadsheet, web browser, a data processing engine, database engine. For example, this is orchestrated. This harness orchestrate this routing of information every single time it touches either processing the context, understanding what is happening, reasoning about what to do, coming up with a plan that you can act that it acts on. That orchestration path is orchestrated by some software. And so this is fundamentally a agent. It deals with short-term memory called working memory, long-term memory just like we do. We have long-term memory and so the memory management system is incredibly important. This entire system is called an agent. The large language model is used to do the thinking and the harness connects everything together just like an operating system. Okay. And so this is the new computing model and this is what an agent it could do incredible things. This is the big breakthrough the simultaneous conver the convergence of large language models that are now able to do a really good job thinking reasoning planning using tools and the fact that we have now these harnesses that manages memory the orchestration uses tools we can now do amazing things. Let me give you some example. This is this is a prompt. This is the prompt. This is the code that is generated and this comes out. This is the input. This is the input and that's the output. Do you guys what do you guys think? It's pretty amazing, right? We use cloud code here, but codeexit does an incredible job as well. Here's another example. This is the input. Create a GIF. Nvidia gen green dots on black scatter form Taiwan 101 building. Morph to GTC Taipei 2026. Morph to Nvidia I logo then scatter and repeat. Right? So you saw that. That was the prompt. Here's the next one. I lost my remote control battery clip. It looks like this. Create a CAD file. It uses a tool. Create a CAD file ready for 3D printing to create a new new one. Make sense? This is now the new computing pattern. Whereas we used to launch an application, click and type, we now replace that with explaining to the AI what we want, our intent. And the AI generates the code or uses tools and produce the necessary output. This is how computers are going to work in the future. This is agentic AI. For two years, we've been building towards this and now it has arrived. Now, one of the big breakthroughs, of course, is tool use. A lot of people have said, you know, Jensen, AI is coming. Agentic AI is coming. Therefore, all of the software companies are going to go out of business. I said it's exactly the opposite because there are going to be so many agents. The world is no longer limited by the number of people. Therefore, those agents are going to use more tools than ever. This is actually an incredible time to be a software company. But the software has to be presented to the agent in a way that the agent can use it. This is a break big breakthrough. And in fact what we have done as you know what Nvidia's treasure is is all of our CUDA libraries. I call them CUDA X libraries. This is Nvidia's treasure. Today we're able to now pres present these CUDA X libraries to agents who can use it much more effectively than even h humans. And so this is a wonderful time for CUDA X libraries. Let's take a look.
20 years ago, we built CUDA, a single architecture for accelerated computing. We reinvented computing. A thousand CUDA X libraries help developers make breakthroughs in every field of science and engineering. CUDA X libraries are tools for agents. CU Litho for computational lithography. CU Opt for decision optimization. QDSS for direct sparse solvers. AIQ for deep research across structured and unstructured documents. Aerial for AI ran. Warp for differentiable physics. Parabicks for genomics. At their foundation are algorithms and they are beautiful.
Heat. Heat. Heat. Heat. Heat. Heat. Heat up here. Heat up here.
A round of applause for math. Math is beautiful. The computing pattern the computing pattern of software is going to change. In fact, let's come back to this. This is the agent. It is the ultimate disaggregated and distributed computing computing model. So many different computers are going to be activated in order to process this agent. The agent consists of model harness, tools and skills and a runtime. All of that is running at different places in a data center. You can think of the model as the brain, the harness as the body, the tools that it uses working in a runtime. Think of it as a workshop. So this is a person, a worker working with tools in a workshop. Of course, this is being done at extraordinarily large scales and each one of those steps are running in a different part of the computer. And you could see the large language model is thinking, context processing, observing, understanding the environment, reasoning, coming up with a plan, and acting on the plan. Every single time that happens, an entire rack of Grace Blackwell MVL link 72 is activated. It's thinking with a large language model. Whenever it uses a tool, a CPU use is used. That tool could be a C compiler, it could be Python, it could be JavaScript or it could be accelerated computing. Today's agents are relatively simple users of tools. Tomorrow they're going to be very sophisticated users of tools, which is the reason why the CUDA X libraries that I showed you are going to be incredibly popular with agents. They solve some of the most important problems the world knows. And all of our CUDA X libraries are now now going to come with skills that the AI could learn how to use. So the CUDA X library some skills basically a manual the AI reads it and go aha that's how you use it. The ability to use these libraries by agents are going to be incredible. And so the tools run on CPUs and GPUs and large language models. The security harness runs on CPUs and a security processor called a DPU. Nvidia's blue field. The orchestration of all this runs on a CPU. This is the entire harness and the CPU is orchestrating all of the work. One of the hardest parts is memory. You could just imagine the working memory is called KV caching. What to remember? Compaction, not just compression, but how to retrieve. Do you retrieve structured data? Do you retrieve unstructured data? What is the ontology? The relationship of all of these different data to itself. That entire processing is incredibly complicated. The memory system, the memory system of AIS is going to cause the storage system to be completely revolutionized. As you could see, every aspect of this computing model, this computing pattern, this new application called an agent is fundamentally different than the way that applications used to run. A whole bunch of software sitting inside a binary, sitting inside an operating system. This is the reason this disaggregated, this distributed, this heterogeneous computing problem is precisely the reason we built our next generation. Vera Rubin, Vera Rubin is not one chip. Vera Rubin is not a GPU only. It starts with the GPU. But Vera Rubin is incredible. This entire thing is Vera Rubin from end to end. It has GPUs Vera Rubin MVLink72. It is orchestrated by Vera CPUs that I'm going to tell you more about the storage systems revolutionary Vera along with CX9 our software stack called DOA the security processor that's inside so that everything is encrypted at rest in motion as well as in use. Everything across this is secure because the AI model is so precious. This is the reason why this entire system obeys confidential computing. Each one of these systems would be a complete revolution in itself. Vera Rubin is the most ambitious endeavor in the history of our company. The whole company worked on Vera Rubin across all 40,000 engineers. Not to mention all of you. All of you participated in the creation of this entire system. Vera Rubin is really a miracle and it's not just one chip. It is so many. Well, it's even beyond that. A long time ago, Nvidia used to be a GPU company. But over the years, we've evolved to become a systems company. You're looking here now for the most complex system, most complex and groundup system ever designed. But ultimately our customers, our partners don't want to buy computers. They want to build AI factories. Which is the reason why Nvidia has really started to transform oursel yet again. You could see so much of our technology is now at the entire infrastructure scale. Our partners are at infrastructure scale. Power generators, cooling systems, the grid providers. So many industrial companies are now part of our ecosystem because ultimately we're trying to build an entire stack just like GPUs, just like when we were building Grace Blackwell MVLink 72, just like now we are building a full stack system so that our customers could build amazing AI infrastructure. Let's take a look.
The world is racing to build AI factories. The largest infrastructure buildout in human history. AI factories are incredibly complex. Every layer, chip, rack, network, power, cooling, grid must be designed together from end to end because compute is revenues. NVIDIA DSX is the blueprint, a reference design for building and operating AI factories at maximum efficiency and profitability. It starts with DSX SIM. With the DSX SIM Omniverse blueprint, partners design and validate an NVIDIA Vera Rubin AI factory before a single rack lands. They plan the layout, simulate the power and cooling, design the network, validate every integration, test every change in the digital twin. The factory powers on. DSXOSS takes over and provisions, operates, monitors, and remediates the infrastructure, turning the installed systems into trusted, multi-tenant, resilient, AI ready capacity. Today's AI factories overprovision power by up to 40%. DSX Max LPS lets operators safely deploy more GPUs inside the same power budget, adding billions in annual revenue. Breakthrough hot liquid cooling at 45° C uses less water and energy. More power going to revenue generating compute. Incredible. Dynamic power allocation steers power from rack to rack, recovering stranded watts, sending them where work is happening. In rack power smoothing flattens peak current spikes and power surges throughout the factory. Teams of AI agents work with DSX Max LPS, continuously coordinating to balance cooling and power to meet workload demand. DSX AI factories are flexible energy assets that operate cooperatively with the grid. DSX Flex reads real-time grid signals and dynamically adjusts factory power when the grid needs relief. 100 gawatts of AI factories will come online before the end of the decade. NVIDIA DSX AI factories run at highest efficiency, produce the lowest cost tokens, and make the grid stronger.
I've shown you ecosystem slides of the past where Nvidia's computing layers and software and software and computing stacks are integrated into other people's platforms, third party platforms and libraries that serves end markets. That was a computing ecosystem. This is an AI factory ecosystem. This is way downstream of all of you. Upstream of me is all of you and downstream of us is this ecosystem. Because Nvidia ultimately is not just building a GPU, not just building a system. We're helping customers build these AI factories, these AI infrastructure that is so immensely complex. Each one of these at one gigawatt level started at 30 2030 billion dollars. It is at 5060 billion dollars and soon it will be 80 hundred billion per gigawatt $100 billion into an AI factory. It must work the first time and it must work right away. The cost of capital is incredible. The complexity is incredible. So as you see we used to design a chip inside a computer and then we simulated a system inside a computer. Today you saw just now everything was built in Omniverse. I've been working with Omniverse with all of you for a long time. This was the dream come true so that we can build these gigantic systems as large as the world wants to build inside a digital framework inside a digital simulator in a digital world long before we build the first break ground and put our money to work. So this is our ecosystem our we call it DSX. RTX is for our GPU, DGX is for our systems and now DSX basically infrastructure because of the work that we do here across this entire stack including our systems and software. It's the reason why we could work with small companies and enable them to be worldclass AI clouds. Every one of these I'm about to show you are small companies just recently and now Coreweave is worth 50 60 70 billion dollars and growing incredibly fast. Recently we worked with Nbius and again they're growing incredibly fast. Each one of these clouds have incredible customers. Cursor, the software coding company, Black Mountain Labs, Image Generation, World Labs, World Foundation model, Revolute, the leading financial services AI company, and Shopify. Here's another one. This is NScale, and their customers are British Telecom, Google. Google is using one of our AI clouds, Thinking Machines, a Frontier Labs company. Super exciting. Here's neighbor cloud in Korea, Bank of Korea, Hyundai. So many incredible companies. Here's one in India, Yoda. Incredible companies. Here's one based in Singapore building in Australia. Together AI AI Singapore. This is one in Indonesia. Each one of these companies, each one of these companies are serving regional as well as global customers. AI is going to run everywhere. Every company will be powered by it. Every region will build it. Indoat here in Indonesia. Here in Taiwan, GMI here in Taiwan, GMI. It's okay to clap. So incredible, incredible incredible companies, incredible opportunity, but all of them need several things. Of course, they need the computing stack. This entire stack underneath this is what made Nvidia famous. All of our hardware and software and libraries, our connection into the world's ecosystem of thirdparty developers makes it possible for anyone to stand up an AI cloud. However, the AI cloud is so complex. Now, this is the software version. This is the computer science version, the money version, the asset version is what I showed you earlier. It's a giant factory. Having this ability alone is not enough which is the reason why Nvidia has become an AI infrastructure company. Now doing this well and becoming incredibly good at dep at helping customers build AI factories and deploying AI factories is incredibly important. And the reason for that is this. Compute is revenue. Now compute is profit. the absence of revenues and profit is loss. And so it's really important to realize that this is when this is an example of an AI infrastructure coming online. It could take it could be coming online quickly. It could take a while. Its throughput could be high. It could be low. Its resilience and reliability could be good or bad. And its lifetime of usefulness could be long or short because this represents 50 60 going to a hundred billion dollars. This curve matters greatly which is the reason why Nvidia is such a great partner working with us because of our fully integrated capability. We didn't just come up with a PowerPoint slide. We created the entire infrastructure. We connected everything together. We built out billions and billions of it ourselves to make sure that everything works well. As a result of that, our time our time to first token, our time to first token, our time to first inference, our time to training turned on is much faster. Second, because our throughput per watt, our tokens per watt is utterly worldclass. And the reason for that is because we integrate everything. We design everything from the ground up. We simulate the entire system and we use extreme code design. Just like I showed you just now with the Vera Rubin rack, everything was designed in order to deliver on this incredible throughput. If your data center, if your factory has one gigawatt, it will not have more. One gawatt means 1 gawatt. That's all the power generation you could do. If you have one gawatt of power, then throughput per watt is revenues because every token is profitable. Every token is revenues. This is the future. Compute is revenues. Performance per watt is your revenues. Choosing the wrong architecture just because the chips are cheaper doesn't translate doesn't make sense. You need to make sure that your revenues per watt the more you buy the more you make. And so tokens per wide. And then lastly, very li oh second, third is reliability. If you ever get a chance to see these data centers, there are so many moving parts, millions of cables. The ability for all of those computers to work harmoniously, reliably is extremely low. It is just extremely difficult. We have now been operating very large scale for a very long time. That experience matters. That difference meanantime time between interrupts extremely important. And then lastly, this is very hard. The lifetime of these systems, the lifetime of these systems, the software is changing all the time. Four years ago, which is in the time of Hopper, AI has completely changed. Six years ago, this is the time frame of Ampear. AI has completely changed. We started out talking about CNN's here. We are then we talked about transformers and then we talked about mixture of experts. Now we're talking about agentic systems. Every single generation, every single few months, the software industry is coming up with new technology. If your architecture is not flexible, if your ecosystem is not rich, then this curve cannot be long. You cannot predict how long your system can last. I can Nvidia systems is all over the world. Software developers start with Nvidia CUDA and by definition therefore the life the ecosystem the useful asset is going to be much longer. The difference is essentially cost. You could think of it as revenues but the other side of revenues is cost. If the life of the asset is long, the TCO is low. This is the difference. This is what it looks like when compute the more you buy, the more you make now. All of you are experiencing this with me. Isn't that right? all of your demand, your factories are working so hard, your people are working so hard all across Taiwan because everybody wants to make money. They realize that AI, useful AI is here. Profitable AI is here. Compute demand is incredibly high and compute demand is the constraint. And so let's go work super super hard and help the world stand up AI factories everywhere. This is why it's so important. I'm so happy here I am standing in front of you. Vera Rubin is in full production. Vera Rubin is in full production. It the the the supply chain we created for Vera Rubin is twice as large as Grace Blackwell. Not Yeah, it's incredible. And And what used to take two hours to assemble one Grace Blackwell rack now only takes five minutes. So not only is the capacity higher, the throughput is a lot faster and we need it all to support the demand. This ecosystem is extraordinary. Millions of square feet has been put online to support Grace Blackwell and preparing now ramping up now Vera Rubin. I want to thank all of you. Vera Rubin is now in full production. Thank you. Let's take a look.
Large language models generate answers. Now AI agents can do work. But processing agentic AI is a whole different kind of problem. Agents observe, reason, plan, use tools. They manage massive context, juggling working memory and long-term memory. They spin up sub agents, specialists on demand. NVIDIA Vera Rubin is a multi-rack pod-scale system built to process Agentic AI and is now in full production. The manufacturing automation and orchestration across the supply chain a miracle to witness. Our journey started when we launched the first AI supercomputer Nvidia DGX1. Over the next decade, we pushed every chip and system to the limit. From Pascal and the first MVLink to Grace Blackwell, the first rack scale AI supercomputer and now Vera Rubin, the first multi-rack pod-scale supercomputer built for the agentic age. It starts at TSMC. The seven new chips that make up Vera Rubin take shape through hundreds of processing steps. 3 nanometer process, co-was R and co-was L packaging, HBM4 memory from Micron SKH and Samsung. The Vera Rubin compute board 6 trillion transistors with over 18,000 components on one board. Vera Rubin NVL72 does the thinking, prompt and context understanding, reasoning, and planning. Next, a new modular compute streamlined with a new PCB midplane design, super chips, connect X9 Super Nix, and Bluefield 4 DPUs, all made in place with no cables for resiliency at AI factory scale, 18 compute trays, nine hot swappable NVLink switch trays, new high efficiency manifolds, liquid cooled bus bars carrying over 5,000 amps, the equivalent of 20 electric cars at full acceleration. Together, 1.3 million components formed this third generation MGX rack design. Congratulations to Microsoft for their operational Vera Rubin MVL72 engineering rack. Congratulations to Dell and Coreweave as well for standing up their Vera Rubin MVL72 engineering rack. Then the Vera CPU rack. 256 CPUs in a single liquid cooled rack. Orchestrating the models, shuffling memory, launching tools. At Foxcon and Quanta, Gro 3 LPX takes shape. 256 Gro 3 LUS across 16 trays, 40 pabytes per second of SRAMM bandwidth for ultra low latency. While MVL72 generates tokens at the highest throughput, Grock LPX generates them at the lowest latency. Vera Bluefield 4 STX where AI keeps its memory. Storage processing accelerated by Bluefield 4 connecting memory, storage, and in-silicon security. and NVIDIA Spectrum X Ethernet photonix. The world's first Ethernet switch with 200 gigabit co-packaged optics. TSMC's coupe process chip scale packaging and ultra high powered laser dies on indium phosphide. Vera Rubin five connected rack scale systems. A supercomputer for AI agents. 150 supply chain partners across Taiwan. Millions of square feet of factory floor, hundreds of sites, chips, packages, systems, and data centers pushed to the limits of size, power, and scale. This is what we call extreme code design. We did this with Taiwan. Together, we reinvented computing for the age of AI. Taiwan was with us at the beginning and here today as we bring Vera Rubin to the world. Thank you, Taiwan.
Ladies and gentlemen, Vera Rubin. Vera Rubin was not just built for AI. AI. Vera Rubin was not built just to run AI. Vera Rubin was built to run agents. This is an agentic system. Imagine the complexity which is the reason why agents is the last computer science breakthrough. It has taken this many years for agents to realize its potential and become useful. It stands to reason that the computer that runs it is the most advanced in the world. This is Vera Rubin. Let's take a look. Can we bring out Vera Rubin, please?
And Janine, do we have the Do we have the racks, the systems? It looks heavy. This is This is Vera Rubin. Vera Rubin MVLink 72. This is the Gro LPX. At the next GTC, I'm going to talk to you about a lot more of this today. We have so much to talk to you about. This is Vera CPU rack. 256 CPUs, all liquid cooled. Let me tell you about Vera in just a moment. This is the Vera Bluefield storage processing system and also security system. And of course this is our Melanox networking the world's first CPO. This is Vera Rubin. Incredible technology all coming together. Now when we built when we built Hopper, we built Hopper as you know for pre-training. Pre-training was the most important application, the most important workload we were working on at the time. Then when we worked on Grace Blackwell, everybody said, 'Jensen, you know, Invidia is really good at pre-training.' Inference is so easy. Do you remember that? People used to say inference is so easy. We could do that, too. But as you know, inference equals money. And the models are so complicated. And to do it at incredibly high response time, fast interactivity and high throughput at the same time is incredibly hard. Which is the reason why we created NVLink 72. Today NVIDIA's token cost is the lowest in the world. Not by 10%, by X factors, orders of magnitude. All because we did extreme code design. All because we understood the computing model. the computing pattern of inference and we were able to create MVLink 72. Now with Vera Rubin it is beyond inference. It is now inference in an agent agentic system. This is Vera Rubin. No cables, no hoses, no fans. What used to take the last time when I showed this to you, we had cables everywhere. The cables were amazing to look at, but now there's a PCB in the middle which connects both sides. What used to take two hours now takes 5 minutes. The reliability and the resilience of Vera Rubin is going to be off the charts. This is our Vera CPU tray. The most advanced CPUs that has ever been built. I'm going to show you that in just a second. And this is our storage tray. Two Vera CPUs, four CX9. Incredible amounts of software. This is our new LPX LPU30, the Gro system designed for very low latency inference. The throughput is delivered by Vera Rubin and extended with MVLink 72. If you want to extend that even further, you can have Grock LPUs. Here we have the Vera Rubin MVLink the switch tray. This is the switches in the middle. And this is revolutionary because of Vera Rubin's because of MVLink72 and the MVLink switches that we created and invented. And this is our Ethernet switches for scale out. What's amazing is we introduced these two systems for Grace Blackwell. These two systems were created for Grace Blackwell and today Nvidia is the largest networking company in the world. I'm so proud of the networking team. This is such an incredible enabler for everything that we do. I'm going to now talk to you about the next major industry we're going to be part of. Thank you, Janine. Thank you, Zen. I think there are 2,000 people back there pulling that. Okay, let's talk about CPUs. Vera CPUs. CPUs built for the age of AI. All of the CPUs until now were created for people. We were the users. We were the users. We were the renters. The way we use CPUs, we live in a world counted by seconds. The way we rent CPUs in the cloud, each one of them more you can more CPU cores you have the more you can rent. The economics of the old the use case of the old CPU and the economics of the old CPU fundamentally different than agents. Agents are impatient. They don't live in a world that is in seconds. They live in a world that's in nanoseconds. When it uses a tool, it wants the response time to be as fast as possible. When it access database, it has to come back as soon as possible. Every moment that the agent is waiting keeps it from going to the next step, the next step, the next step. It is vital that we make the CPUs as low latency as possible, as interactive as possible. So we created Vera CPU for the age of AI. Now inside our system it's used for three different ways. The first way of course is Vera Rubin for thinking and inside the Vera Rubin rack. They're already two CPUs. As you know we are building and selling millions of Vera Rubins. We have sold millions of grace black walls. Nvidia already is one of the largest CPU makers in the world. Vera in the Vera Rubin rack are two CPUs. One for orchestrating and managing the GPUs, managing the KV cache, dealing with all of the software that runs in the rack. We also have the grace blue field that is used for security and isolation. The Vera compute is used for the harness, the orchestration of the AI models, tool use, accessing the database. And the data servers are right here, Vera Bluefield, the fastest storage, fastest storage servers, the fastest storage system the world has ever made. And the reason why this is so vital is because agents are accessing memory accessing memory so incredibly fast. These systems, the storage server and the CPUs are now the critical path of the most expensive part of the data center. This is the most expensive for a good reason. The economics, the economics of the AI factory is tokens and the tokens are created here. And so of course you want to manufacture and generate as many tokens as possible. This is where you put all of your economics and this has to not be in the way. And so Vera CPU has great pressure on the Vera on the CPU architecture which is the reason why we built a brand new architecture from the ground up. A CPU the world has never seen before. We call it Vera. This is CPU for agents. All the CPUs of the past we built for humans. This CPU is built for agents. Well, there are four things to keep in mind. The four takeaways. The first takeaway is that the instructions per clock of Vera has to be incredibly good because we need the latency to be short. We need the processing time. Singlethreaded performance, not throughput. Singlethreaded performance has to be world class. Absolutely the best singlethreaded performance. Which is the reason why the IPC, the instructions per clock of Vera is so high. is the highest in the world. 10 instructions fetched, decoded and executed per clock. Number one. Number two, the bandwidth necessary to move data in and out for the CPU has to be utterly world class. The second thing is bandwidth per core. The third is just bandwidth period. We're moving. Remember I said earlier agentic systems is fundamentally disaggregated and distributed disaggregated and distributed. When computing is disaggregated and distributed networking becomes the problem. Therefore, we have to move the data around as fast as possible between the CPU cores and between the CPU and the storage, the CPU and the GPU. The bandwidth around the system and inside the CPU core has to be utterly world class. This is the first CPU that's been built a long time that is literally at theoretical limits with a fabric that connects all of the CPU cores. That is speed of light 3.6 terabytes per second. No chiplet taxs, no chip boundary crossings because we need to have everything because the CPU cores are talking to each other with extremely high bandwidth. They're not rented core per core per core. They're all working together. The cross-sectional bandwidth of Vera is off the charts. It's the first one to be PCI Express Gen 6. It is also the first one to have LPDDR DDR5 with 1.2 terabytes per second. Three times two to three times the bandwidth of the highest performance CPUs on the outside, three times the bandwidth on the inside. The bandwidth per core and the bandwidth period is world class. Now remember I showed you earlier the number of CPU cores the number of CPUs is going to be quite high and the reason for that is very simple we created CPUs for humans in the past and humans there only 1 billion of us there will be billions of agents and these agents are going to be using the CPUs with very little patience because the cost of the GPU they sit next to is too high and therefore too valuable, too precious. Therefore, these CPUs are going to be both performant, but they also have to be extremely energy efficient so that we can cram as much CPU as we can into the factory without taking away power from the token generation, which we know is how we make money. These four properties, instructions per clock or single threaded performance, bandwidth per core, the total bandwidth around the chip and inside the chip and energy efficiency defines Vera. It is absolutely world class. When you compare it to the highest performance x86, it is just off the charts. When you compare it in real singlethreaded performance, real performance, it's off the charts. It is incredible to be able to deliver 5% improvement on CPUs. It is incredible to be able to deliver 10%. But this kind of performance speed up is just unheard of. This is Nvidia Vera. What do you think? Let's take a look.
Agentic AI changes the role of the CPU.
The CPU is now the conductor and the GPU is the orchestra. Traditional CPUs were built for a different era, maximizing cores per socket. Slice them up, virtualize, rent by the hour. In the age of agents, the CPU is now a bottleneck to GPU utilization, directly affecting token throughput, latency, and user experience. NVIDIA Vera is the CPU built for the agentic loop, combining NVIDIA's custom data center CPU core with the scalable coherency fabric for the right balance of performance cores and bandwidth to maximize AI factory output. At the heart of Vera is the NVIDIA Olympus core built for modern data center workloads, branch-heavy Python runtimes, tool calls, and sandbox code execution. Each core is tuned for throughput. A neural branch predictor evaluating two taken branches per cycle. A 10-wide decode engine brings in more work each cycle. A large out-of-order engine keeps instructions moving. Advanced prefetchers with a novel graph engine anticipating the next data path. But fast cores only matter when data arrives correctly and on time. Vera is the first CPU to use LPDDR5X memory while correcting multiple errors simultaneously without compromising bandwidth. Vera achieves 40% lower peak memory latency versus x86, keeping cores fed on time through retrieval, analytics, and sandbox execution. NVIDIA's second-generation scalable coherency fabric unifies all 88 Olympus cores on a monolithic mesh with separate dies for memory and IO. Cores are not split across chiplets, enabling 50% faster core-to-core communication than traditional CPUs. And memory-coherent NVLink chip-to-chip connects GPUs directly to the fabric. Beyond GPUs, NVLink chip-to-chip can scale Vera up to multiple sockets, enabling massive bandwidth between CPUs. Vera delivers 1.88 times the agentic sandbox performance of x86 CPUs. Standalone Vera racks run agent sandboxes, tools, code, and data pipelines. Tightly coupled to Rubin GPUs, Vera keeps accelerated workflows moving. NVIDIA Vera, Bluefield 4, STX powers context memory and AI storage, compute, networking, storage. Vera is the CPU for the age of agents.
This is going to be our new major growth driver. The reviews are already coming out and it's pretty good. That's pretty good stuff. Now remember, Grace and Vera are also the most highly qualified CPUs in the world of AI because every single data center, every single cloud, every single enterprise, every company that works with NVIDIA on AI has already qualified Grace. The entire software stack has already been optimized for Grace. Every company will be qualifying Vera. Vera will be the most optimized agentic CPU in the world simply because it's going to go with Vera Rubin, simply because we made the big hard switch. In fact, during Grace Blackwell transition, the biggest risk was going from external CPU x86 into Grace Blackwell. That transition was extremely dangerous, but we did it with incredible execution. Now Grace is literally synonymous with Grace Blackwell. When people say Blackwell, they say Grace Blackwell because it is utterly now everywhere. Every company's software stack has been optimized for it. Everybody's security stack has been optimized for it. And now here comes Vera. I'm super excited about that. Now look at some of the performance numbers.
Speed up says one thing. It is extremely hard to speed up SQL. SQL, the most famous domain-specific language DSL that has ever been created. Before SQL, you know, before CUDA, there was SQL. Before OpenGL, there was SQL invented by IBM. Today it is the structured database engine of the planet. Everybody uses SQL. This is SQL running three times faster. Not 10% faster. Not 25% faster. Three times faster. Incredible. This is real time. The next one is real-time stream processing. Remember your AI is going to be not just reading documents. Your AI is going to be watching for telemetry, especially inside a factory, inside a stock exchange. You're going to be looking for telemetry continuously. The burst of data that's coming in goes into a CPU. This is Vera CPU running real-time stream processing for New York Stock Exchange. Lynn Martin, the president of New York Stock Exchange, has been so gracious to partner with us. This system is run all over the world in real-time stream processing. Vera CPU, six times faster, all because of the bandwidth, the single-threaded instruction execution, the bandwidth inside between the cores, the bandwidth outside. Vera is completely revolutionary. That's Vera.
You know, X factors is something you talk about when you're talking about GPUs. It is quite rare that somebody talks about X factors on real workload, real workload that is associated with CPU. So I'm so proud of the team. You guys did such a great job. We have an extraordinary roadmap coming. But what's really exciting is almost everybody is supporting Vera. They're as excited as we are. This is Vera opening up. It's opened up a brand new market. Agents. Agents is a new workload. We built CPUs for humans in the past. We need CPUs for agents. Agentic systems. Their properties are different. Why would the old CPUs be the same? We are building millions and millions of errors. Millions of errors. And to go to market with us, Taiwan's ODMs and computer makers, all the OEMs, and you could see the early adopters. The early adopters are the agentic companies. This is the beginning of a new market, a market that never existed before. It's not going to take away from the old markets, but this is a new market. CPU for agents. And this market will surely be larger than the last, and the reason for that is because there'll be a lot more agents than there are people, and then the agents are very impatient. So NVIDIA Vera CPU, thank you.
This is the most important slide really. This is the takeaway. The takeaway here is that this is the application pattern. This is the computing pattern of the next decade. Agents, harnesses, orchestrating large language models. Every company will run it. Every company will be an agent company. Every company will have agents running inside. Every company will see that agents will need its own operating system. Every company's asking us how do we run agents safely? How do we build agents for our own workloads? And so we have the NVIDIA agent toolkit for enterprise AI. You've seen me build this in plain sight. Almost everything that NVIDIA does, as you know, at every GTC, if you go back and look at my GTC five years ago or 10 years ago, you will see today this you've seen me talking about for several years now because we've been building for this moment. There are four things that companies need in order to build agents as a service or build agents to operate. The first thing you need is you need models. Of course, large language models, the smarter the better, the cheaper the better, the faster the better. The second is you need a harness to orchestrate the whole thing. The third, these models want to use tools and these tools come with skills and I showed you CUDA-X libraries. Those are going to be amazing tools for the agents in the future. And then lastly, you need a runtime. You need the operating system that holds it all together. This is the NVIDIA toolkit for agents. It includes models that you can modify. NVIDIA's world-class open models. And I'll show you more. You can run agents from anybody. You could run Cloud Code, incredible agent, CodeX, incredible agent. You could run it inside this harness called OpenShell which will be highly secure for you inside the enterprise. The shell protects the agent, keeps it grounded in security policies. Privacy is protected. Its rights and privileges are given, its identity protected. And so this OpenShell is being adopted all over the world. NVIDIA OpenShell is open source. You're going to see so many companies adopt it. Red Hat, Canonical, Microsoft, it's going to be adopted everywhere. This is the runtime and this runtime is fully optimized for the NVIDIA AI platform which is everywhere. So you can run OpenShell in any cloud, on-prem, and even on device. So you have tools and libraries that they can use. You have models that you can modify or use as-is, or you have agents. This could be OpenClaw, Hermes, another incredible harness. These agentic harnesses can now run on-prem or for you anywhere. Okay. So four things and this represents the operating system of the modern enterprise.
Now how do we use this? One of my favorite use cases of agents is chip designers. It is the single most important thing that NVIDIA does. And so of course we have to partner with Cadence to build Super Agent, a chip design super agent. It is orchestrated by CodeX or clock code. It has RTL and architecture diagrams or schematics or specifications as input and whatever you need to fix. And together we created some super agents that are optimized for the NVIDIA runtime with Neotron. And let's take a look. It's really incredible.